
Research seminar Artificial intelligence Machine learning
- Date: May 8, 2026
- Duration: 1:21:02
- Speakers: Artiom Lipinski
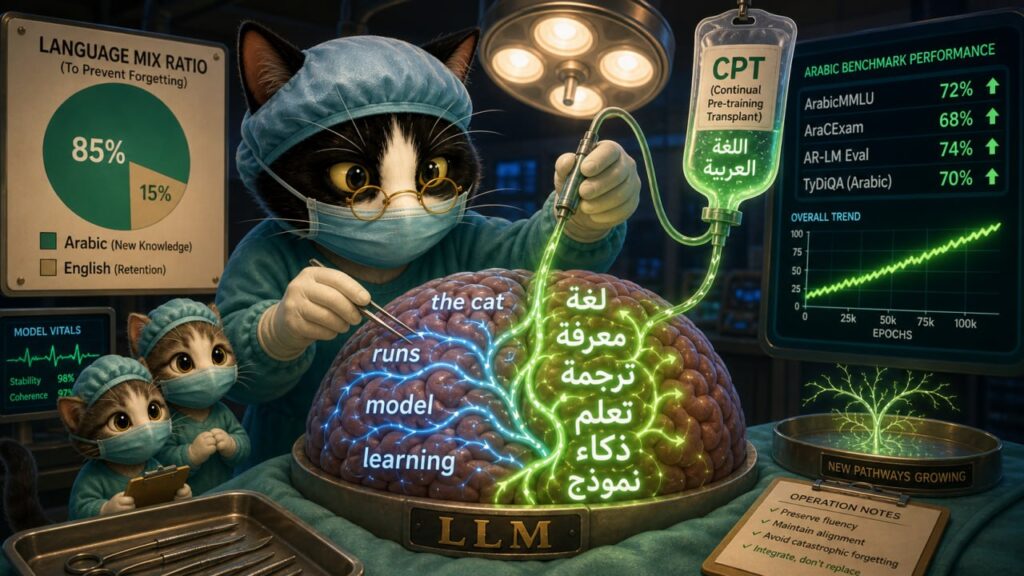
Arabic is one of the most widely spoken languages in the world. However, modern language models still perform significantly worse on Arabic than on English or Chinese. The reason is straightforward: there is a severe shortage of high-quality Arabic data available in the public domain, while most existing models have been trained primarily on English-language texts.
This talk presents the development of an Arabic language model capable of meaningfully understanding and generating Arabic text while remaining compact enough for practical deployment.
The presentation will cover:
— how to collect and curate a large, high-quality text corpus from scratch;
— why mixing languages in the training data can be beneficial rather than detrimental;
— the complete pipeline for adapting an LLM to a new language, from data collection to supervised fine-tuning (SFT), including practical guidance on how to execute each stage efficiently and avoid common pitfalls.
The results are relevant to anyone working on adapting LLMs to low-resource languages, as the approaches discussed extend far beyond Arabic.